DINOv2 — Linear Probe
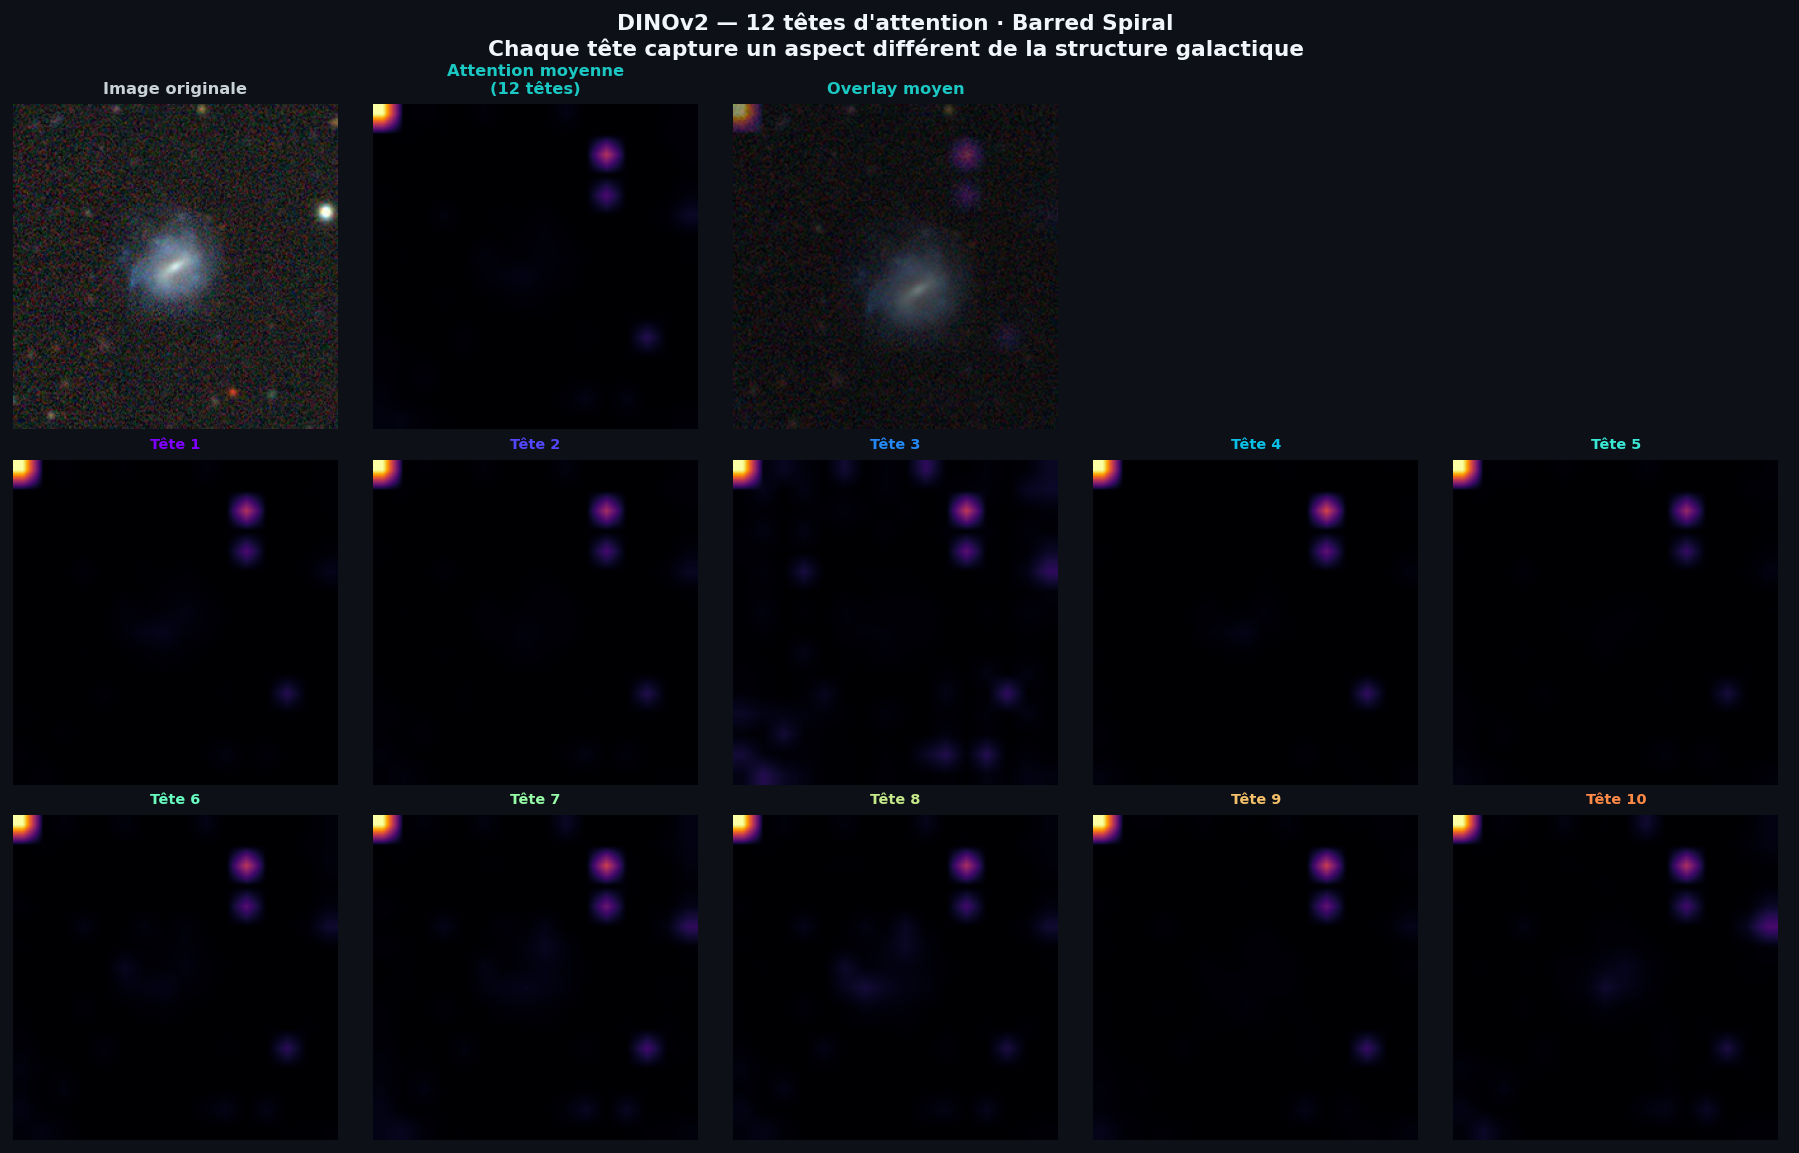
DINOv2 ViT-B/14 (86.6 M parameters, 12 blocks, 12 heads, patch size 14) was trained by self-supervision on natural images. The probe asks: without any astronomical training, how much morphology is linearly decodable from its features?
Protocol
- Resize each image to 224×224 and take the CLS token (768-dimensional) of the frozen backbone for all images; cache in
dinov2_features.npz. - Fit a logistic-regression probe on the training split; evaluate on the test split.
Key results
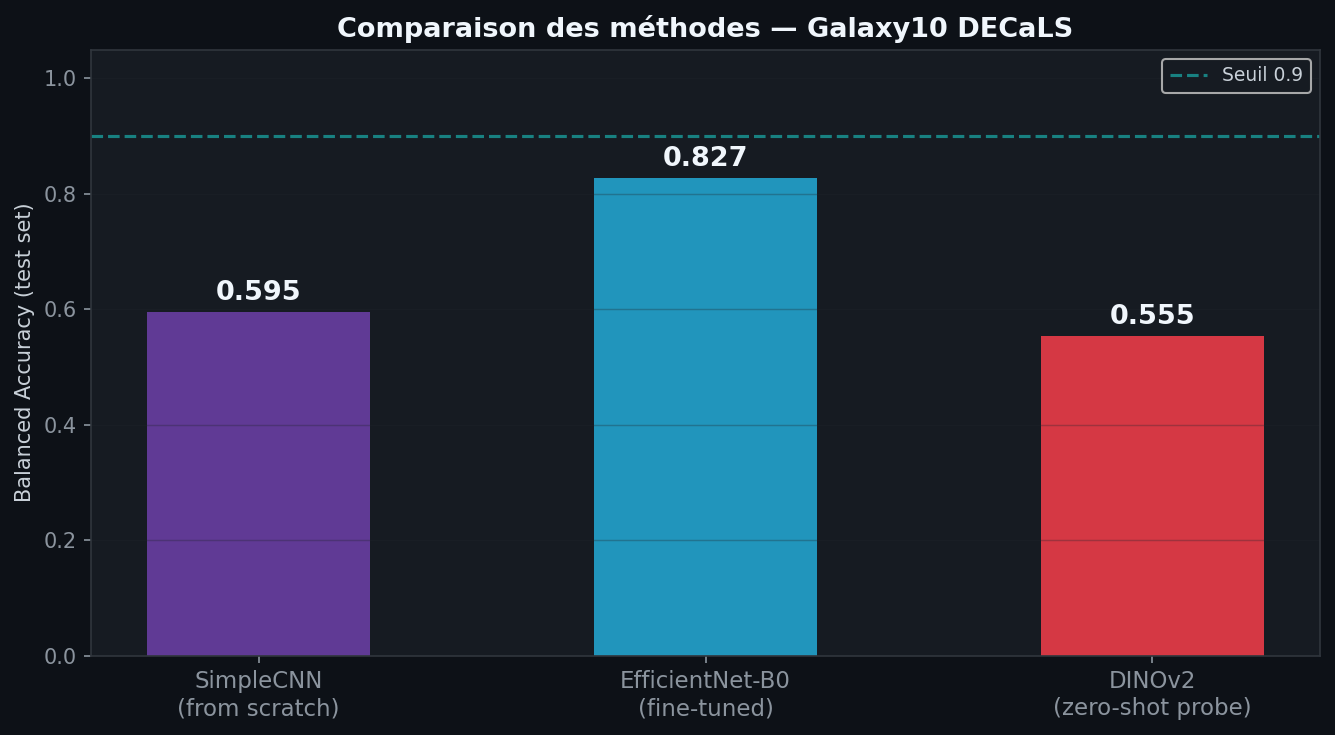
_facts/astrovision/FACTS_INDEX.md §3 and shown when hovering over a number.Frozen DINOv2 features give 55.5% balanced accuracy, below a small CNN trained from scratch (59.5%). Natural-image features alone are not enough for galaxy morphology; fine-tuning recovers and exceeds the CNN baselines.
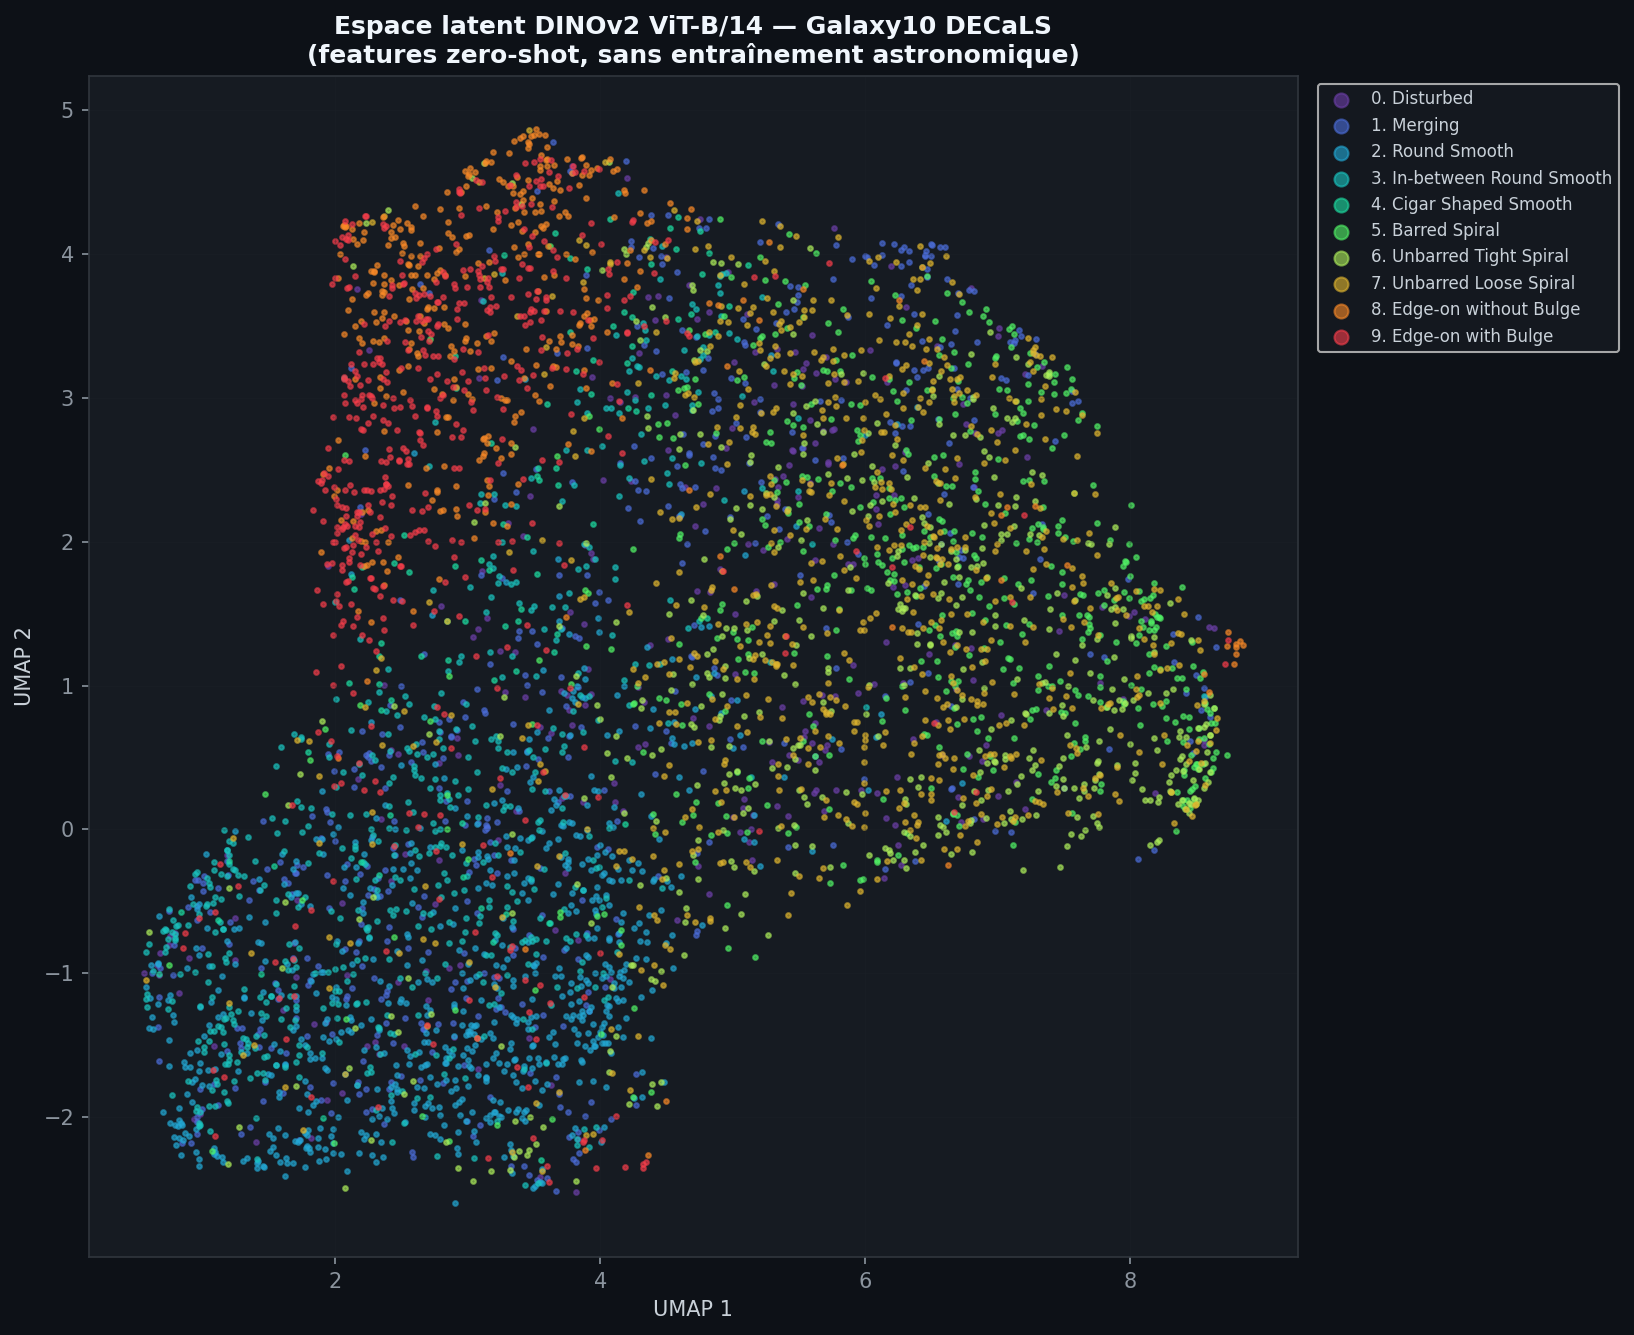
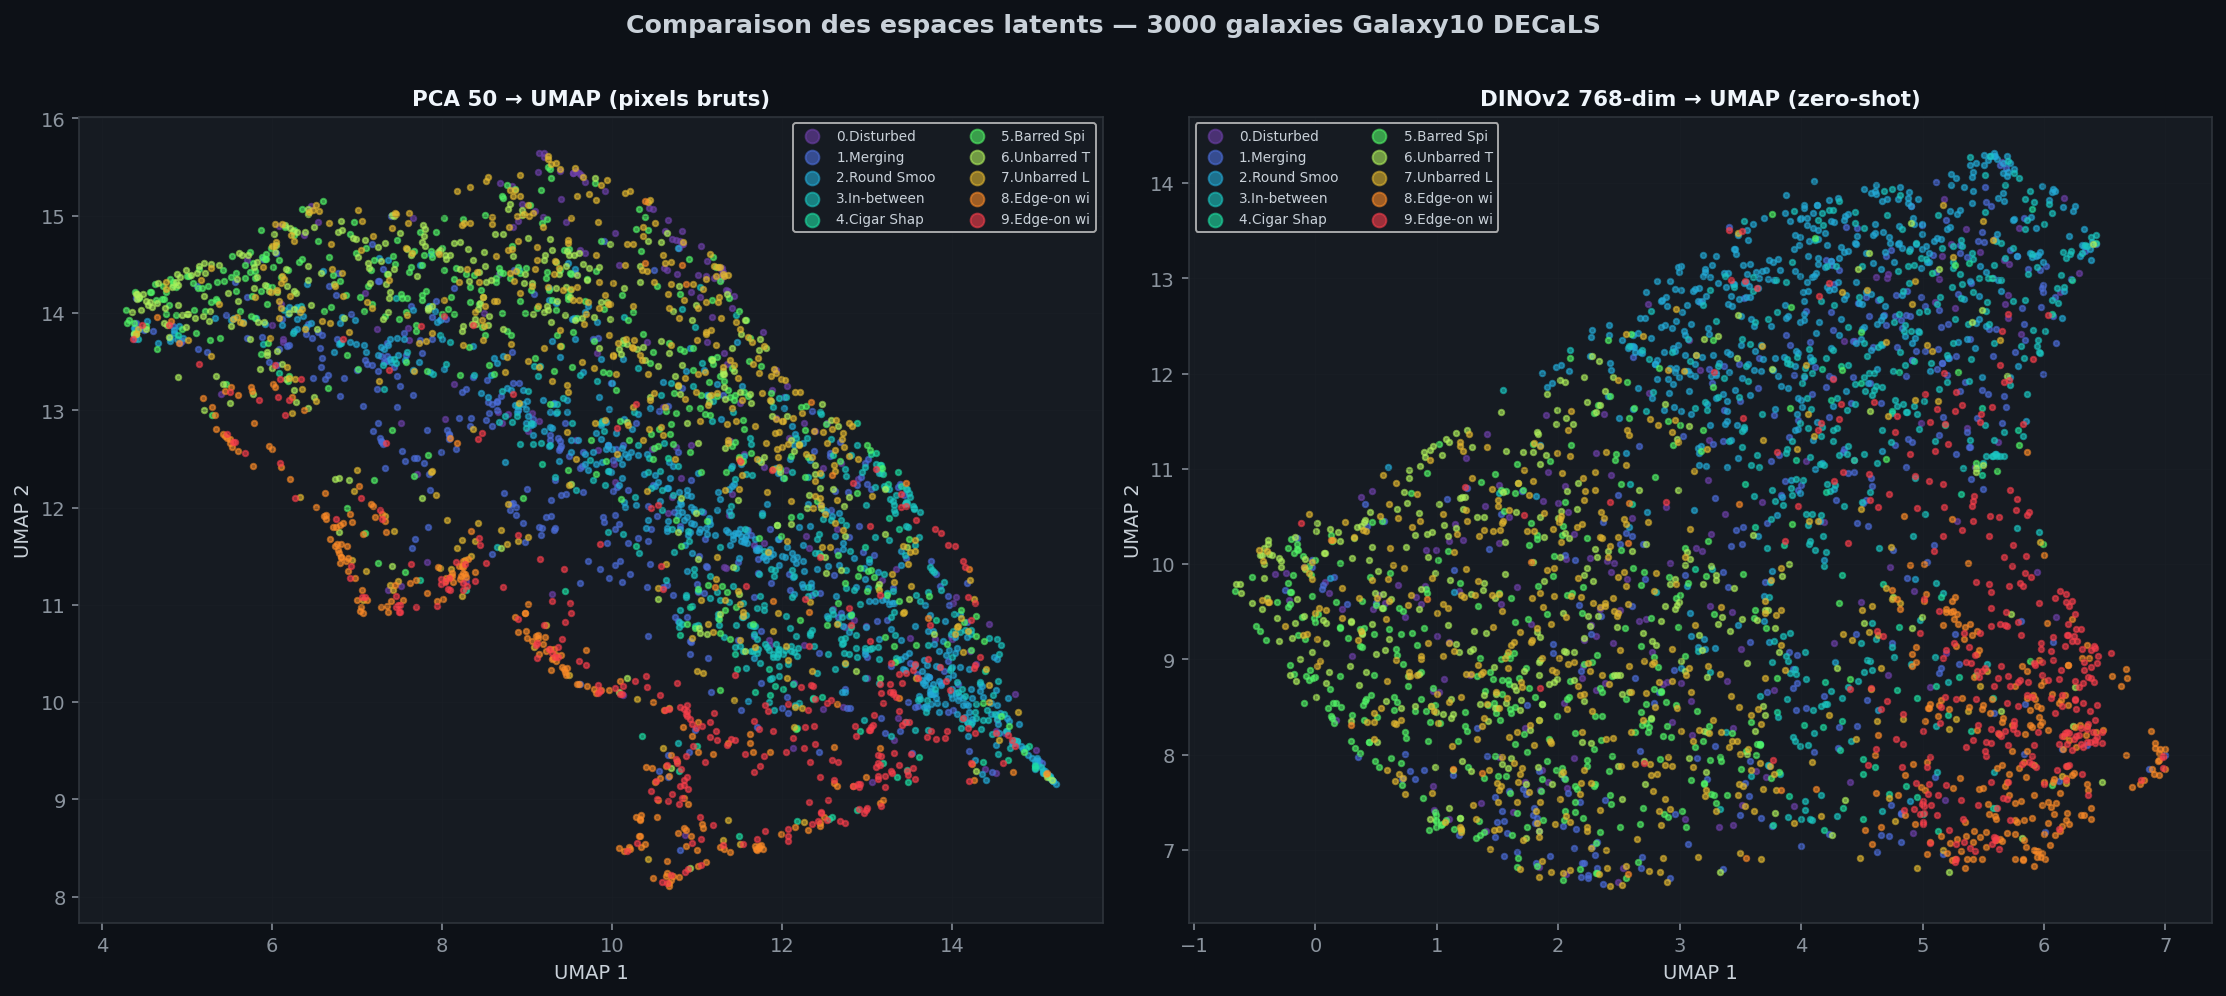
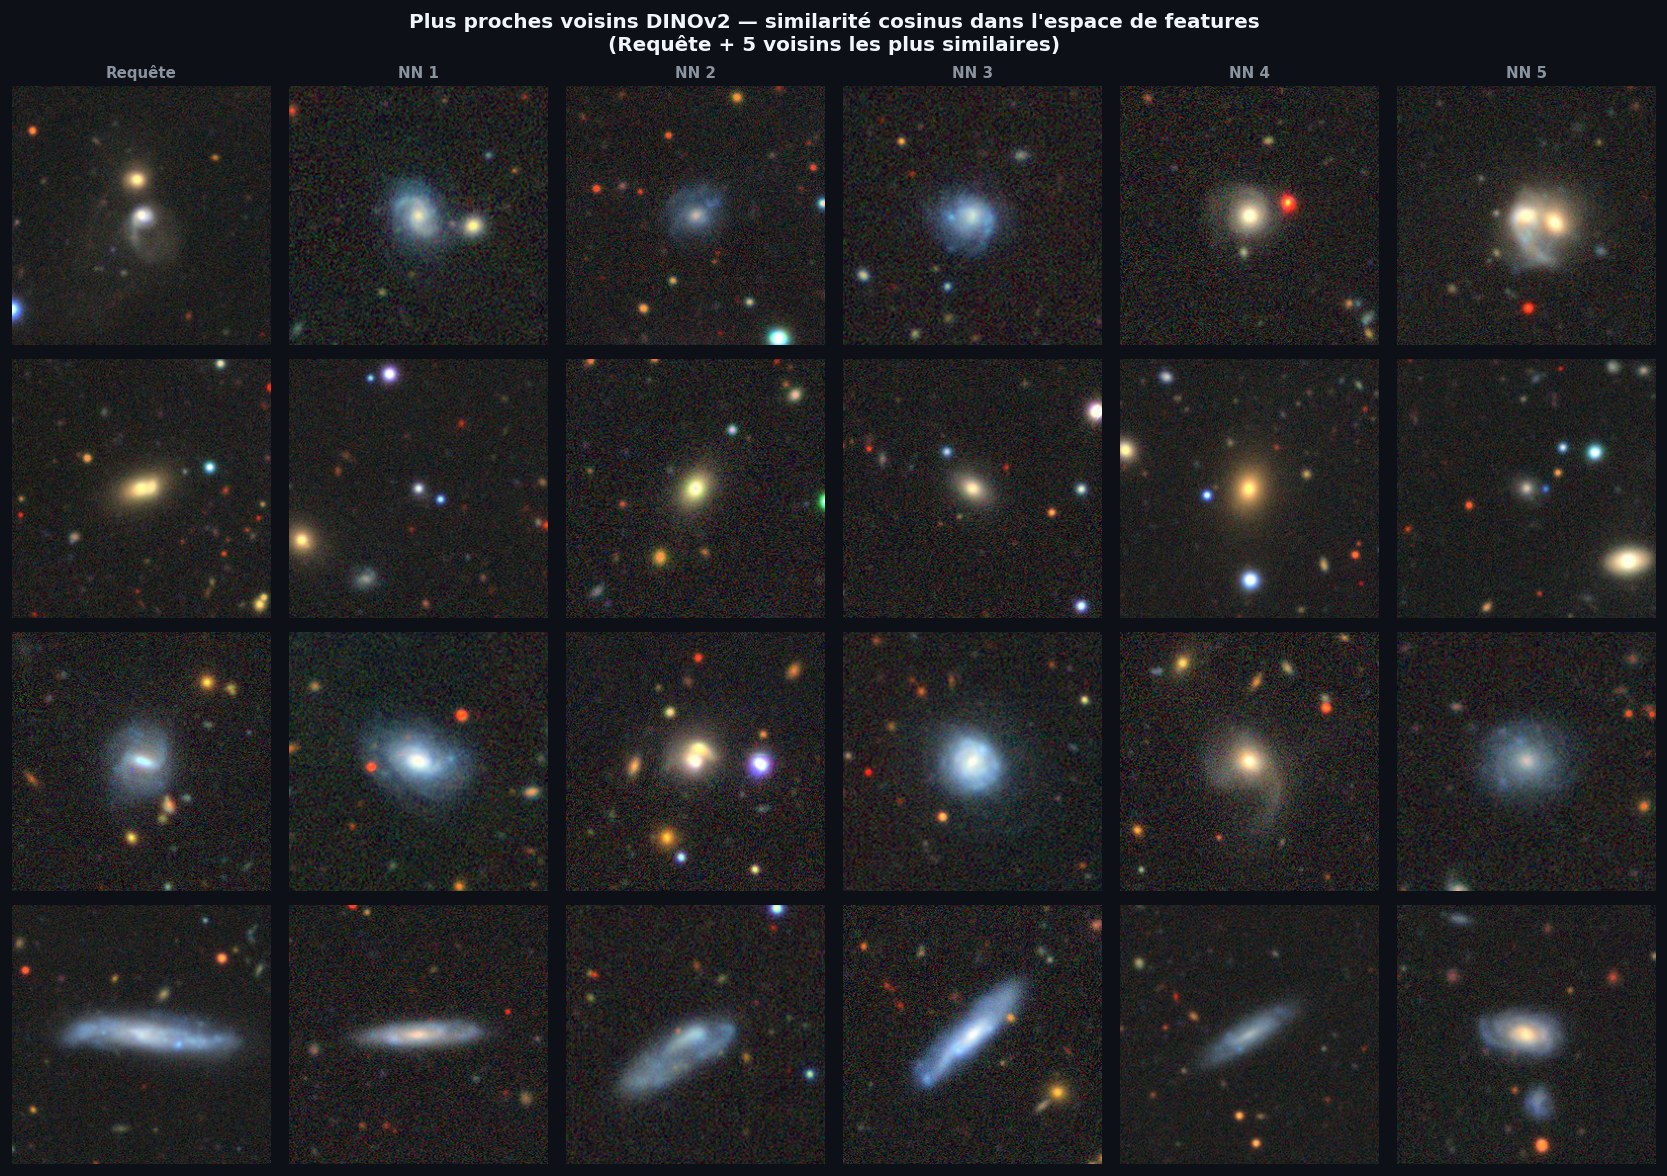
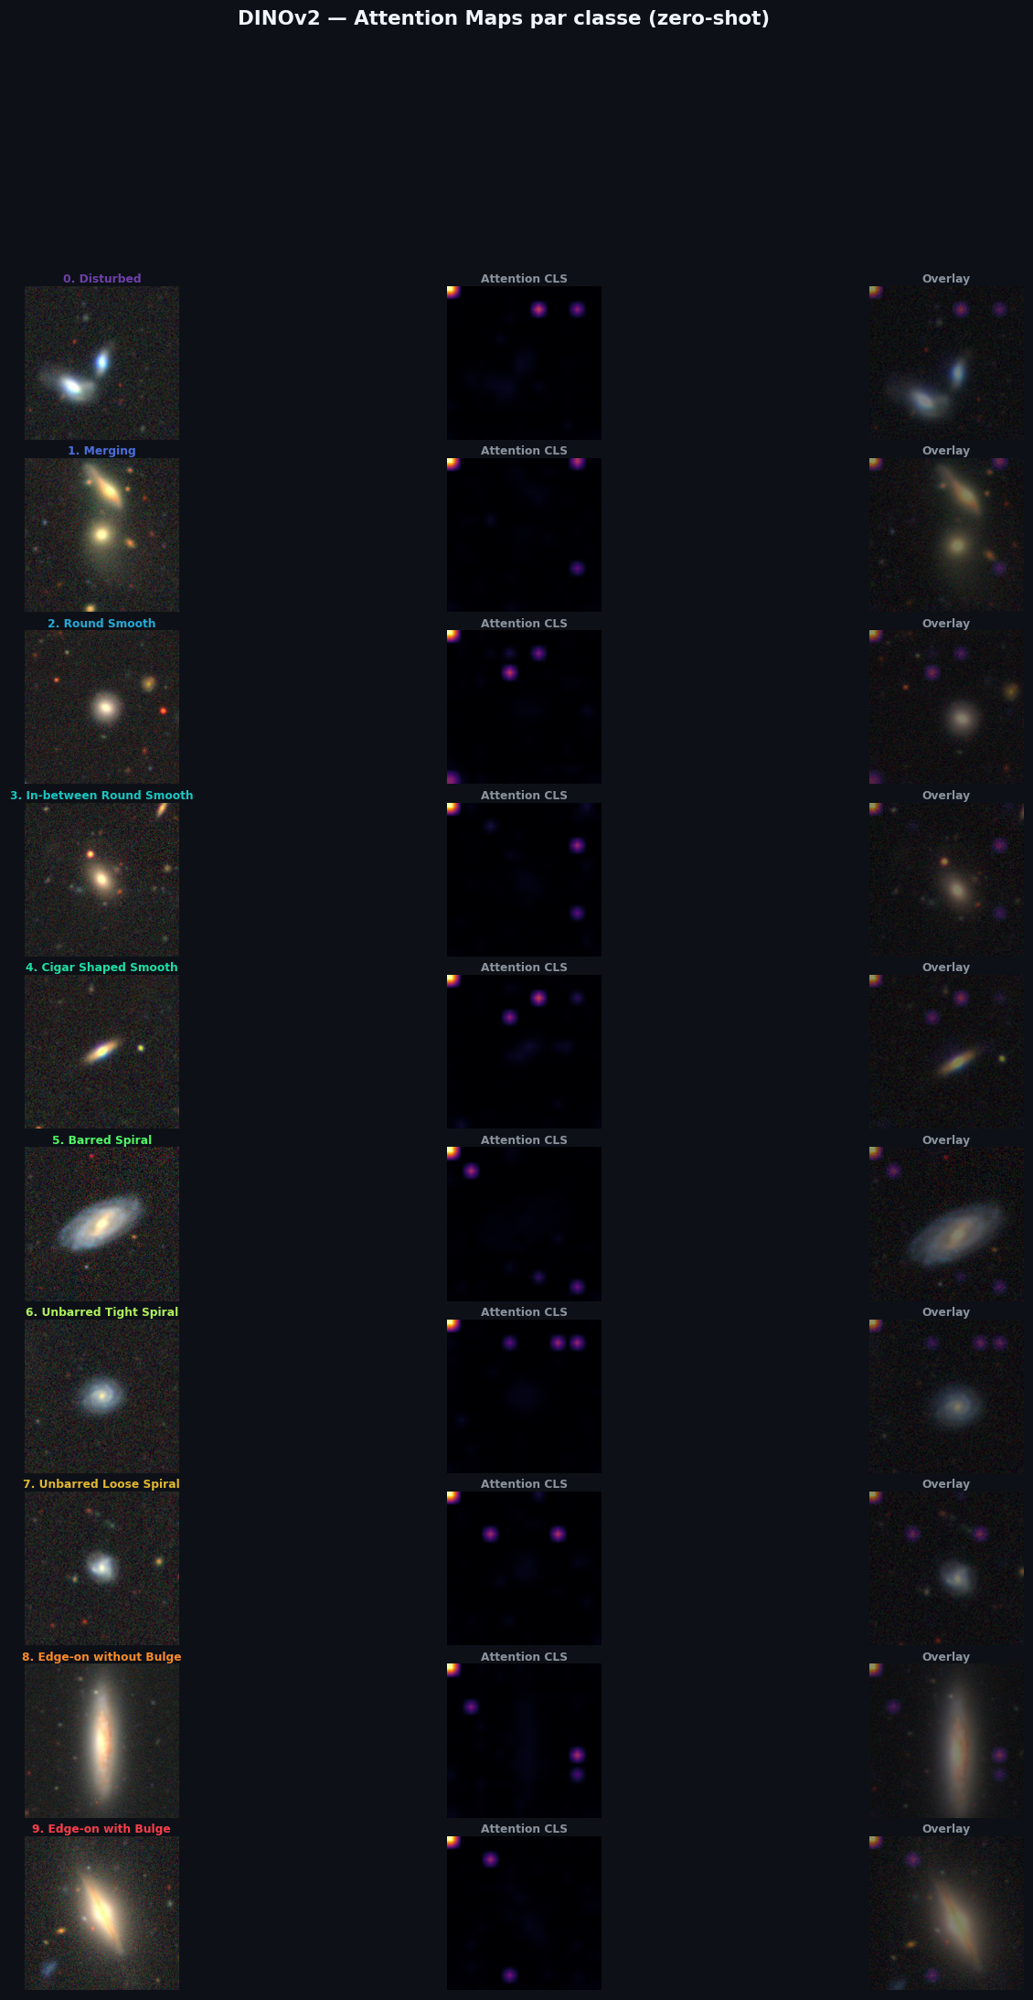
The same features nevertheless show structure without supervision: neighbours in feature space are often of the same class, and a UMAP of DINOv2 features separates the classes more cleanly than a UMAP of raw pixels (qualitative, figures below). The first principal components also correlate with morphometry and colour — see Physical Interpretation.
Three values circulate: 0.5545 (test set, notebook 03, retained here), 0.550 (validation set, used as head initialisation in notebook 04) and a rounded 0.555 in the project README.